The Cost Model: Why You Pay What You Pay
The billable call can include instructions, replayed history, tools, generated output, and sometimes reasoning tokens, even when the latest user message is short.
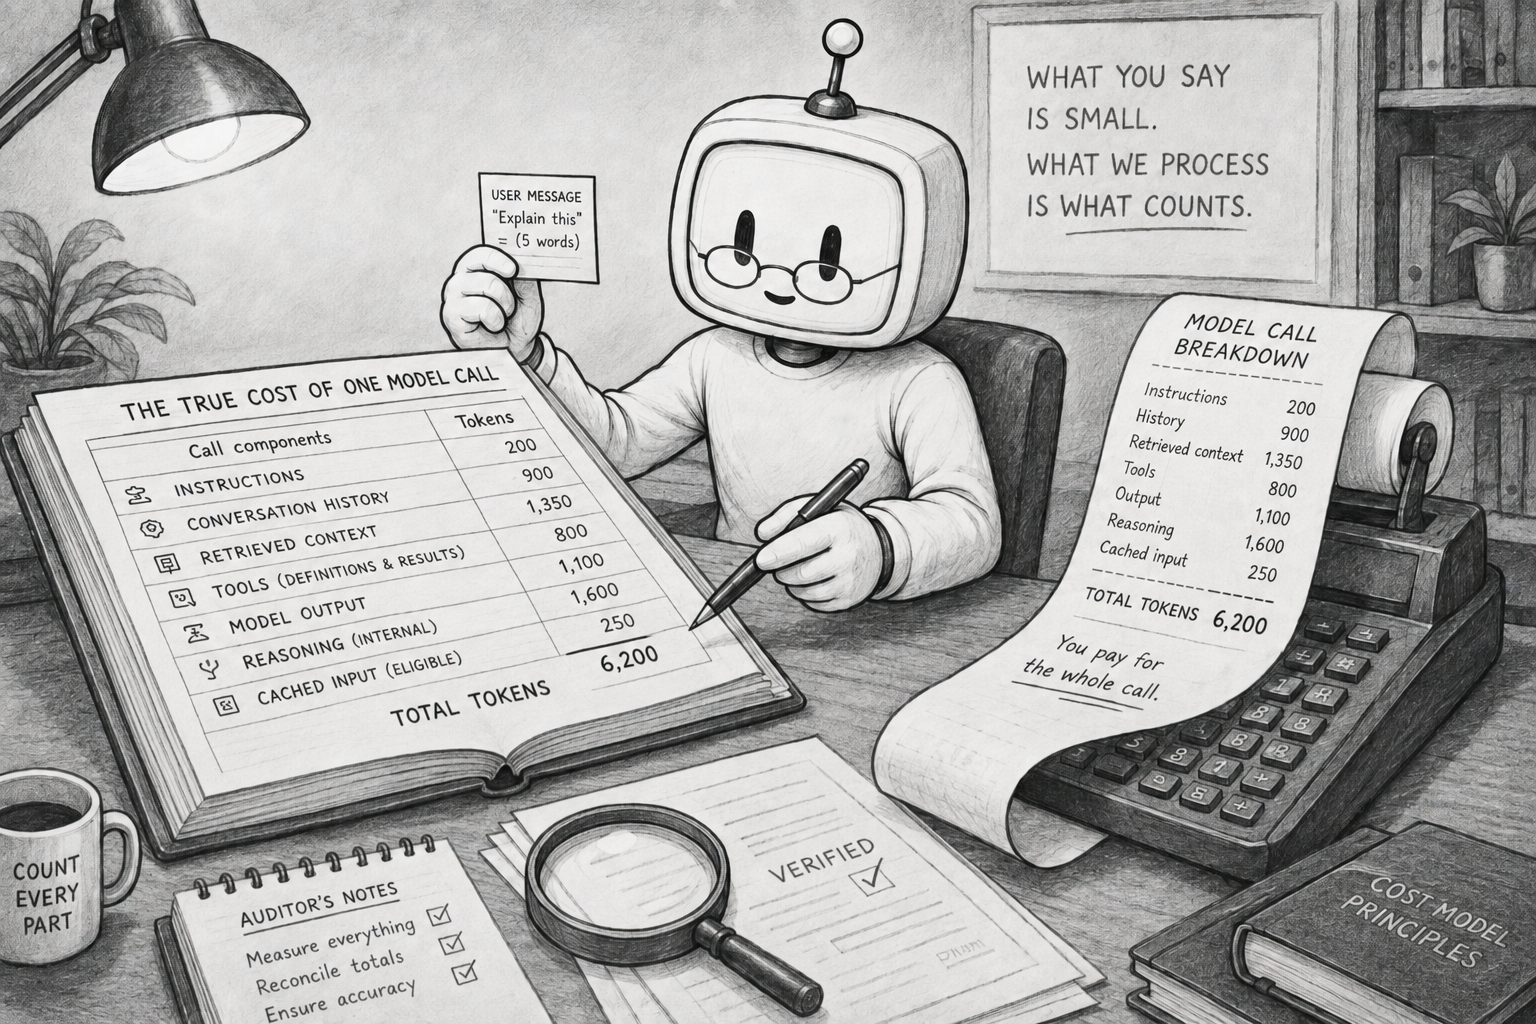
A user types five words and receives a surprisingly expensive response. The five words are not necessarily the billable request.
The application may also send instructions, earlier turns, retrieved evidence, tool definitions, and output constraints. The model may generate a long answer or use reasoning tokens that are not shown as ordinary response text. Cost follows the effective call and the provider’s accounting rules, not the size of the chat box.
This lesson avoids a price table on purpose. Prices, discount categories, and model names change. The durable skill is being able to explain which parts of a call create token pressure and why that pressure grows.
Start with a token inventory
Providers commonly distinguish some combination of these categories:
- Input tokens: instructions, history, user content, retrieved text, tool definitions, tool results, and other model-visible context.
- Output tokens: content generated by the model, including text or structured output.
- Reasoning tokens: internal reasoning budget counted by some models and APIs, with visibility and billing rules that vary.
- Cached input: previously processed input that a provider recognizes and may price differently under specific caching rules.
Not every provider exposes or bills every category in the same way. External tools can also have their own compute, network, or vendor cost outside the model API. The response’s usage metadata and current provider documentation are the evidence for a real calculation.
A conceptual price calculation might multiply counted token categories by their respective rates. It is not safe to collapse that into characters typed x one universal price.
Why a short follow-up can be a large call
Conversation continuity often works by carrying state forward. If the application sends the full relevant transcript on every turn, later requests include more input than earlier requests.
Consider round teaching numbers:
Turn 1 input
  instructions        200
  replayed history      0
  tool definitions    150
  latest user text     50
  -----------------------
  total input          400 tokens

Turn 2 input
  instructions        200
  replayed history    150
  tool definitions    150
  latest user text     50
  -----------------------
  total input          550 tokens

Turn 5 input
  instructions        200
  replayed history    900
  tool definitions    150
  latest user text     50
  -----------------------
  total input        1,300 tokens
The user typed the same amount each time. The input grew because the system carried more history.
Some APIs let the client reference a prior response or a persisted conversation instead of resending a visible message array. That can simplify application code, but it does not imply that all prior context becomes free. For example, an API may still count earlier input tokens when it threads a response chain. Check the specific accounting contract.
Tools cost context before they run
A broad tool catalog has a cost surface even if no external function is selected. Names, descriptions, argument schemas, and tool-support instructions can enter model-visible context.
After a tool is called, more content can accumulate:
- The model emits a structured tool request.
- The application or provider executes the operation.
- The tool result is added to a later call.
- The model generates another response from the expanded context.
The external operation may have a separate price, and every additional model invocation has its own input and output accounting. Do not confuse “the tool returned no user-facing text” with “the step had no cost.”
This is one reason to expose the tools relevant to the current task rather than attaching an entire platform catalog to every call.
Output is a budget you control
Input optimization receives most of the attention, but generated output can be a major cost driver. A request for a 5,000-word report creates a different budget than a request for five ranked findings.
Useful controls include:
- set an output limit appropriate to the task;
- request a concise structure when concise output is genuinely sufficient;
- stop repeated boilerplate at the application layer;
- split large deliverables when separate calls improve context selection or review;
- avoid generating prose that a deterministic program could compute more reliably.
An output cap is a ceiling, not a promise that the answer will be complete before the limit. A cap that is too tight can cut off important content or produce a failed structured response.
Streaming is not a token discount
Streaming affects when output arrives, not which token categories exist. If a streamed run is cancelled, inspect the reported usage: any cost difference comes from the changed execution and the provider’s cancellation policy, not from the typing effect itself.
Control cost by designing context
Effective cost control is selective. It asks what the call needs to succeed, then removes or reshapes what it does not need.
- Measure complete requests. Record provider usage fields by model, route, and task instead of estimating from user-visible text.
- Select relevant history. Do not replay unrelated turns merely because they share a session.
- Compact with care. Summaries can reduce input, but omitted details may reduce correctness.
- Limit tool exposure. Supply the smallest tool set that still supports the task.
- Constrain output deliberately. Match response length and structure to the actual consumer.
- Use caching where it is supported and measured. Cache eligibility, invalidation, and discounts are provider-specific.
- Set operational budgets. Apply per-request and workflow limits so a loop cannot spend without a bound.
Every reduction has a possible quality cost. Removing a policy, a requirement, or the one log line that proves the failure can make the answer cheaper and worse. Cost optimization is therefore an information-design problem, not a race to the smallest prompt.
The growth pattern to recognize
If each new turn adds roughly the same amount of text and every later request replays the entire history, the input for an individual call grows with the conversation. The cumulative tokens processed across the full session grow faster still because early turns are counted again in many later calls.
Real systems can alter that curve with compaction, selective replay, retrieval, caching, or provider-managed state. Those mechanisms have their own tradeoffs. The prediction to keep is simpler: an unbounded transcript is not free memory.
“I am billed only for the new message and answer.”
The latest message may be the smallest part of the call. Inspect instructions, replayed state, retrieved context, tools, generated output, reasoning accounting, and any additional model turns before explaining the cost.
Read the usage record as a systems trace
A useful cost investigation joins three views:
- Payload: what context and controls the application assembled.
- Execution: how many model calls, tool steps, retries, or cancellations occurred.
- Accounting: which input, output, reasoning, cached, or provider-specific units were reported.
Together they explain why a call cost what it did. A short user sentence cannot.
That closes the path through one request: state is restored, an envelope is assembled, the real payload fills a finite window, output may stream, and the complete execution is accounted for. The model call is only one layer, but once that layer is visible, its behavior stops looking like hidden magic.
References
- Conversation stateOpenAI
- Function callingOpenAI
- Tool use with ClaudeAnthropic
- Prompting best practicesAnthropic